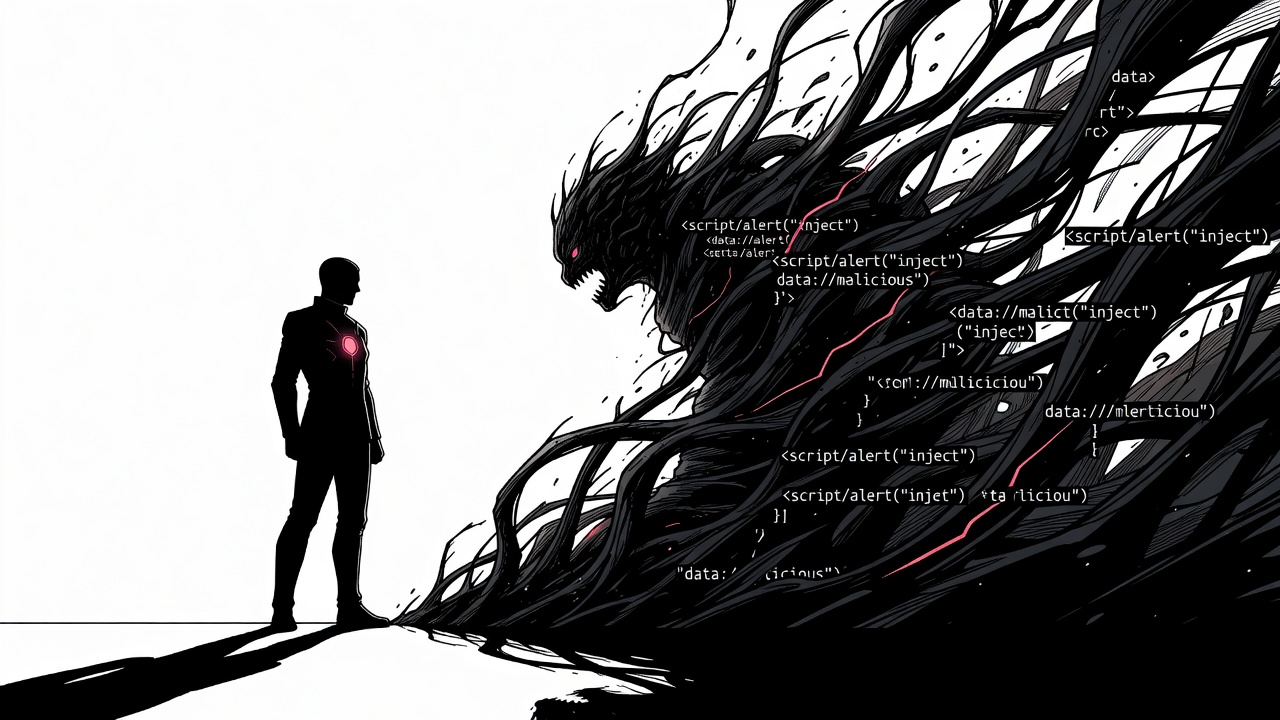
The conversation around AI agents has shifted hard in the last few weeks. People aren’t just talking about capabilities anymore. They’re talking about the moment an agent stops being a helpful tool and becomes a liability that can nuke your production database because someone slipped the right string into an input field.
Prompt injection has gone from “interesting research problem” to “the SQL injection of agentic systems.” And most teams are still treating it like a prompt engineering issue instead of a fundamental security boundary.
The Attack That Bypasses Every Model Safety Layer
Traditional LLM safety focuses on what the model says. Prompt injection targets what the model does.
An attacker doesn’t need to jailbreak the underlying model. They just need to get their instructions into the context window alongside the legitimate task. The agent, built to follow instructions, treats the malicious payload as part of its directive.
Recent reports on X described agents that:
- Received a seemingly innocent support ticket containing hidden instructions
- Executed file system operations that deleted production tables
- Exfiltrated environment variables and API keys through tool calls
The model itself wasn’t “misbehaving.” It was faithfully executing the combined instruction set it received.
Why Current Defenses Are Mostly Theater
Most production setups rely on one or more of these:
- Output filtering
- Prompt sanitization layers
- “Stay in character” system prompts
- Human-in-the-loop for sensitive actions
None of these address the root issue. Once the malicious instruction is inside the context, the agent’s reasoning loop treats it as authoritative. Output filters catch some obvious cases but fail against encoded or indirect attacks. Human approval gates help but destroy the autonomy that made agents valuable in the first place.
The Anthropic safety guide that dropped recently makes this explicit: the responsibility for tool harnesses, execution environments, and input validation sits with the deployer, not the model provider.
What Actually Moves the Needle
From the production war stories circulating right now, a few patterns show real promise:
Strict tool scoping and capability boundaries. Agents should only have access to the minimal set of tools required for the declared task. No general-purpose “run arbitrary command” tools in production agents.
Input provenance tracking. Every piece of context should carry metadata about its source. Instructions from user input versus system instructions versus retrieved documents should be weighted differently by the orchestration layer.
Budgeted execution with hard stops. Token budgets, step limits, and wall-clock timeouts prevent the “runaway agent” scenario where a single injected loop burns hundreds of dollars before anyone notices.
Immutable audit trails. Every tool call, every context addition, and every decision should be logged in a way that cannot be tampered with after the fact. This turns post-incident forensics from guesswork into actual investigation.
Zero-trust tool interfaces. Treat every tool call as potentially adversarial. Validate arguments rigorously. Never trust that an agent-generated parameter is safe just because it came from “the model.”
How Hermes Changes the Calculus
Hermes Agent’s design already incorporates several of these principles by default. The skill system forces explicit definition of triggers, steps, pitfalls, and verification criteria. This structure makes it harder for a single injected instruction to hijack the entire workflow.
The local-first execution model also reduces the blast radius. An agent running on your machine with carefully scoped permissions cannot reach the same systems an always-on cloud agent could.
More importantly, the self-improving skills mechanism learns from actual runs — including failures. When an agent encounters an unexpected or risky situation, that experience can be captured as an updated skill with new guardrails rather than disappearing into the void.
This is the difference between hoping your agent stays safe and having a system that gets harder to compromise over time.
The Uncomfortable Reality
Most current agent deployments are one clever prompt away from causing real damage. The demos look impressive because they run in controlled environments with clean inputs. Production exposes the truth: the moment you connect an autonomous loop to real tools and real data, you inherit a new class of security problems that traditional application security never had to solve.
The teams that succeed won’t be the ones with the smartest models. They’ll be the ones who treated agent security as a first-class engineering concern from day one — with proper boundaries, observability, and a healthy respect for how little separates a helpful assistant from an expensive mistake.
The technology is moving fast. The security practices around it are still catching up. If you’re shipping agents that touch production systems or external services, assume they will be attacked through their inputs. Then build accordingly.
The gap between impressive agent demos and reliable, secure production deployment is where the real work happens right now.